Author: Laxmi Gunupudi
-
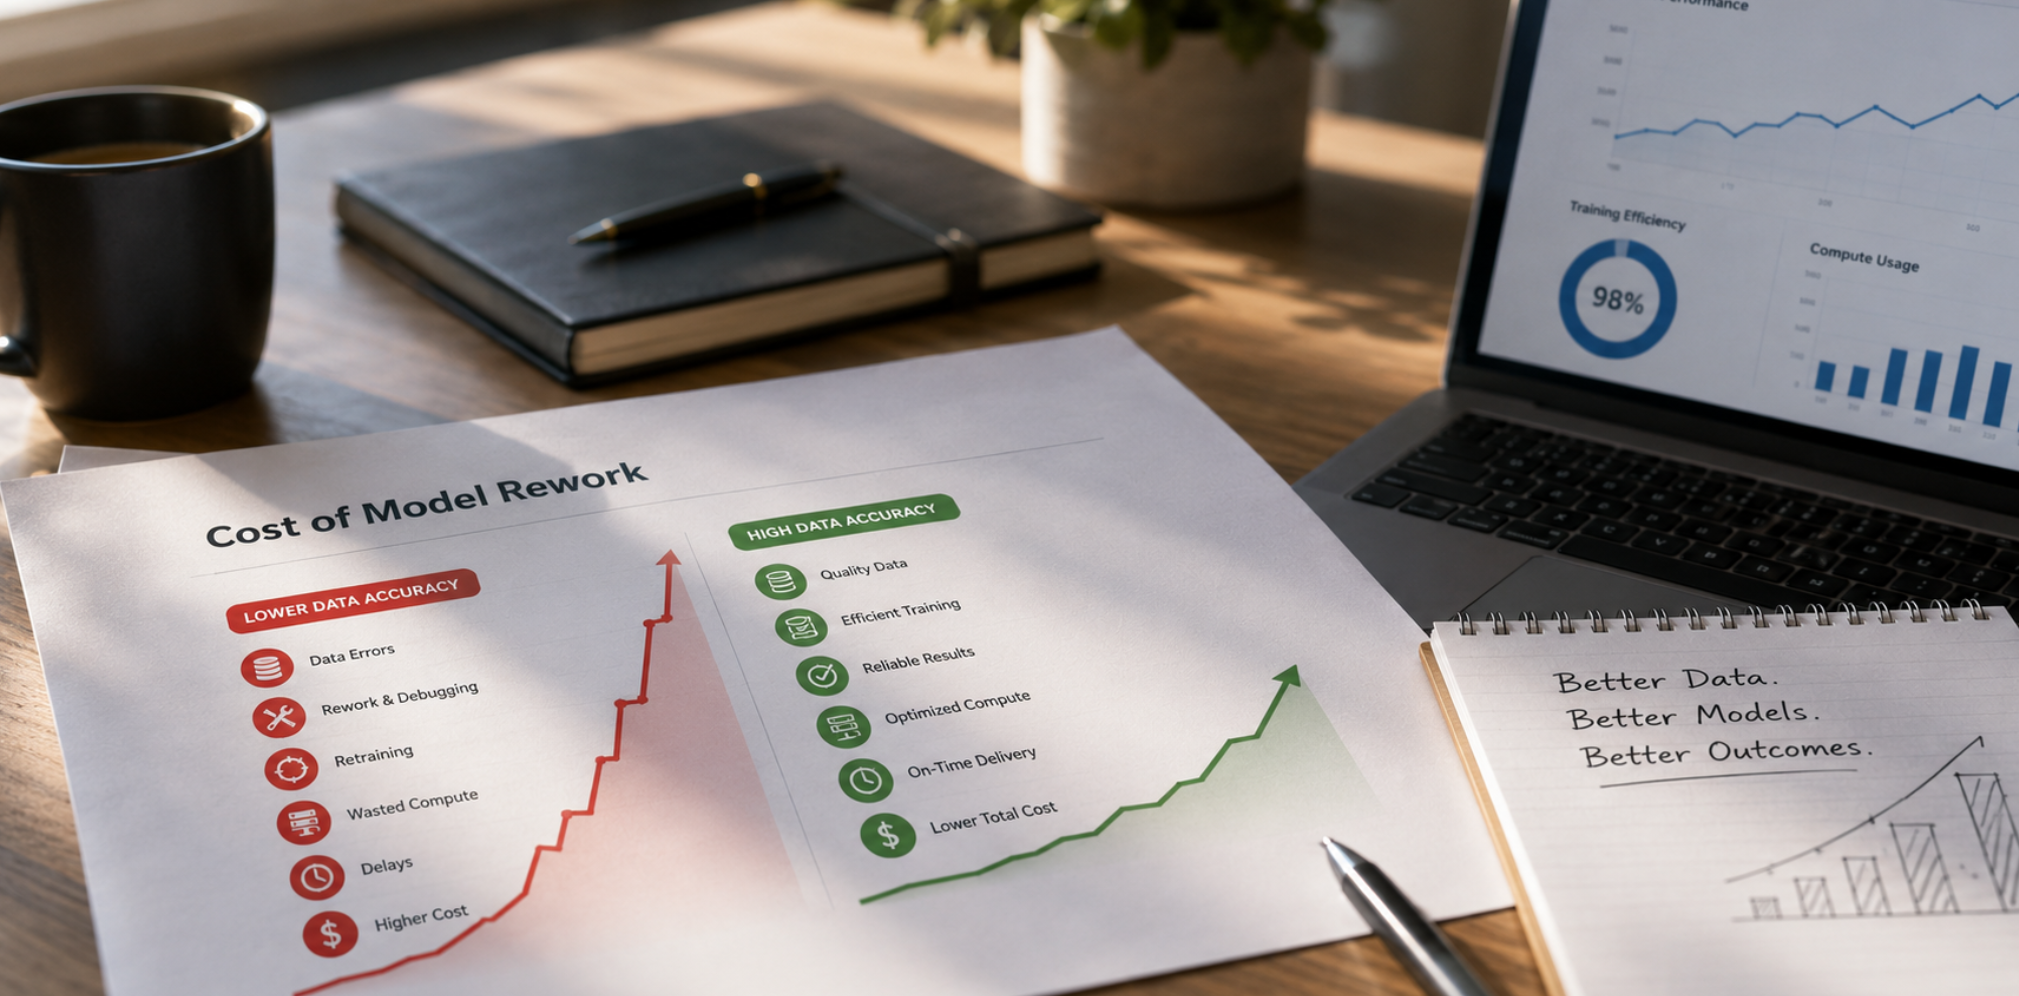
The True Cost of Model Rework
How 99% SLA Accuracy Saves 3x in Training Budget Executive SummaryFor CFOs, VPs of AI, and enterprise ML leaders, data annotation vendor procurement is often treated as a commodity purchase. Line items favor the vendor offering the lowest upfront per-task unit price ($0.15 vs. $0.35/task), a seemingly immediate 57% budget reduction.But evaluating AI data annotation…
-
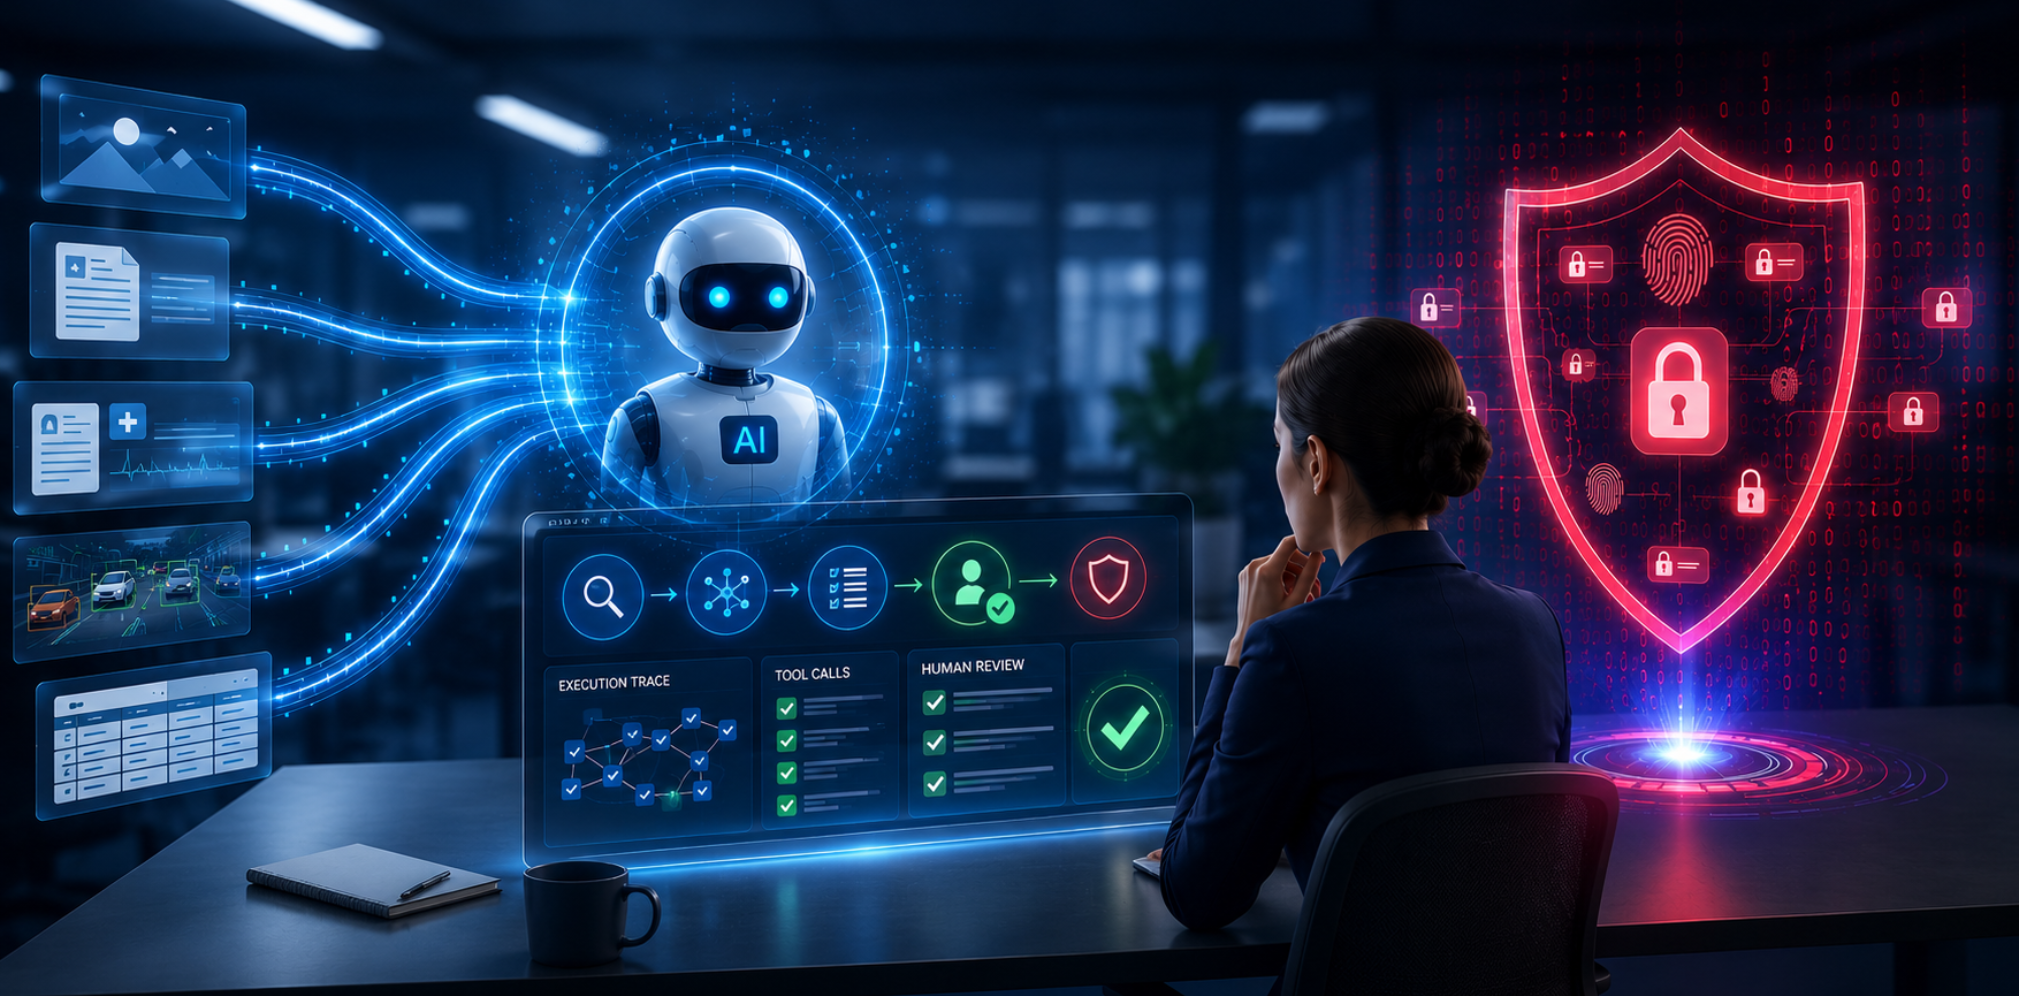
Evaluating AI Agents in Production: Why Automated Metrics Fail Without Human-in-the-Loop
KEY TAKEAWAYS • The Core Problem: Traditional benchmarks (MMLU, SWE-Bench) and automated evaluators fail because they evaluate single-turn text outputs rather than stateful, multi-step execution traces.• Silent Failures: Autonomous agents can pass automated checks with HTTP 200 status codes while executing flawed intermediate logic or causing unauthorized environment side effects.• The Solution: Enterprise reliability requires…
-
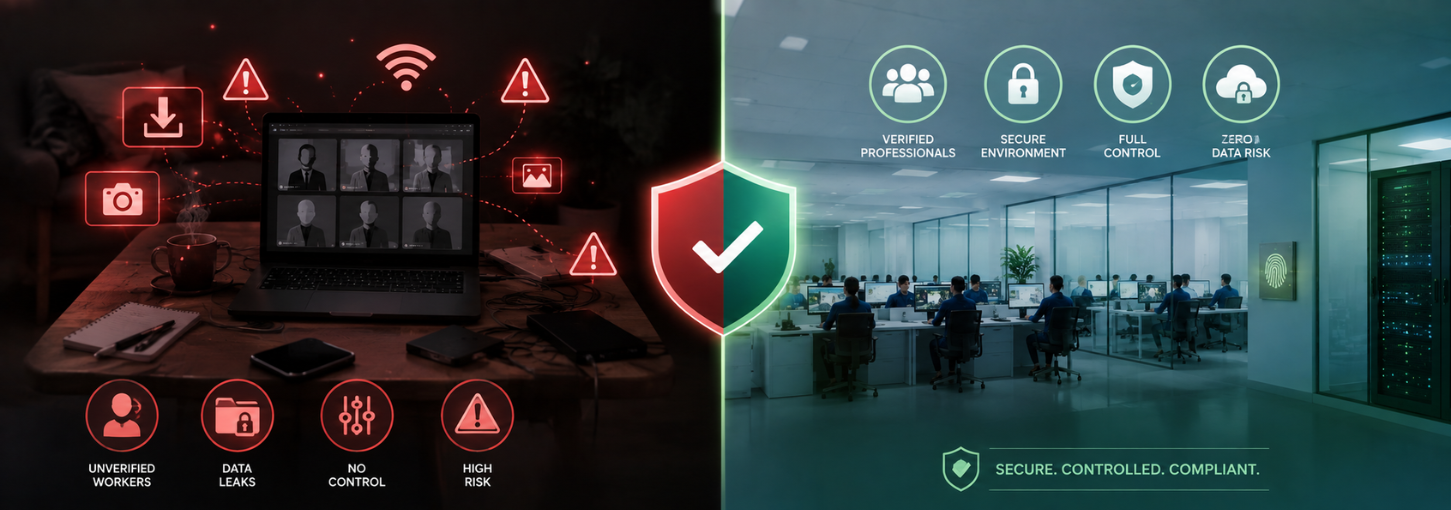
The Invisible Risk in Your AI Supply Chain: Why Crowdsourced Data Is an Enterprise Liability
Picture this: Your engineering team spends $10 million hardening your cloud perimeter, installing military-grade encryption, and enforcing Zero-Trust access controls. Your AI model is state-of-the-art, trained on proprietary trade secrets. But while your front door is locked like Fort Knox, your back door is wide open. Where is that back door? In the unvetted, anonymous…
-

The AI Workforce Evolution: Building the Human-AI Hybrid Enterprise
The 2026 Core Paradigm: Transitioning enterprise AI from experimental pilots to production-grade deployment requires shifting the narrative from workforce displacement (‘Will AI take jobs?’) to value-driven Human-AI collaboration. The primary bottleneck in scaling Small Language Models (SLMs) and autonomous agent architectures is no longer raw compute power, it is domain context, governance, ethical guardrails, and…
-
Why Your Marketplace AI Keeps Getting It Wrong – And How Human-in-the-Loop Quality Fixes It
Your AI model is only as reliable as the data that trained it. Most marketplace AI teams know this in principle. Few have built the quality infrastructure to act on it. The result is a pattern that repeats across e-commerce platforms at scale: a model that performs well on benchmarks but degrades in production —…
-
Enterprise Data Annotation in 2025: Platforms, Pipelines, and Getting Both Right
Most enterprises don’t have a data problem. They have an annotation problem. The models are ready. The infrastructure exists. What consistently breaks production AI is the quality, consistency, and continuity of the labelled data feeding it. Choosing the right annotation platform and connecting it properly to your MLOps pipeline is where reliable AI operations are…
-
Beyond the Scan: Mitigating Shrinkage and Enhancing Trust with AI-Driven Data Verification for Autonomous Stores
In autonomous retail, shrinkage prevention isn’t about better cameras or more sophisticated algorithms. It’s about systematic data verification. Autonomous stores deliver on their operational promise: frictionless shopping experiences eliminating checkout lines through computer vision and AI. The technology performs as designed. Hardware functions reliably. Yet operational outcomes vary dramatically across deployments. Some stores struggle with…
-
Agentic AI: Foundations, Maturity, and the Framework for Reliable Enterprise Deployment
Introduction: The Shift from Prediction to Action Artificial intelligence is undergoing a quiet but profound shift. For the past decade, most enterprise AI systems have been designed to predict: classify a document, rank a lead, recommend an offer, generate a response. These systems operate within well-defined boundaries. They take an input, compute a prediction, and…