Training data is important because a machine learning model can only learn what its data shows it. Accurate, well-labeled, and representative machine learning training data leads to reliable predictions. Poor, biased or incomplete data leads to a model that makes mistakes, no matter how advanced the algorithm is.
Sometime around the end of the 2000s, most of us were already helping machines learn without realizing it. You may remember typing two distorted words into a box before you could log in or submit a form. That was reCAPTCHA. One word checked that you were a human and not a bot. The other was a word from a scanned book that software couldn’t read yet. Every correct answer helped Google digitize text from its book archive.
In other words, millions of internet users were quietly preparing data for machine learning. That early, crowd-sourced effort captures what AI teams still do today: turn raw data into clear, labeled examples that machines can learn from.
This guide explains why AI training data matters when building a machine learning model, how data labeling and validation work, and what good training data looks like in practice.
What Is Training Data in Machine Learning?
Training data is the set of examples a machine learning model learns from. In supervised learning, each example pairs an input, such as an image, a sentence or an audio clip, with the correct answer, called a label. The model studies these pairs until it can predict the right answer for new inputs on its own.
AI model training is a lot like teaching a kindergarten student. You have to describe every small detail of an object: its size, colour, shape and use. Show a child enough correctly labelled pictures of cats and dogs, and they learn to tell them apart. Show them blurry pictures, or mislabel half the cards, and they get confused.
Machines work the same way. Supervised learning models and reinforcement learning systems both depend on the examples they are given. That is why the training data has to be rich, accurate and of the highest possible quality.
Why Is Training Data Important While Building Machine Learning Models?
Training data is important because it sets the upper limit on how good a model can become. Better algorithms and more computing power help, but they cannot make up for data that is wrong, incomplete or unrepresentative.
The quality, accuracy, relevance and availability of training data shape a model in four main ways:
- What the model knows: a model has no knowledge beyond its data. If an image dataset contains no night-time scenes, the model will struggle at night.
- How accurate it is: wrong labels teach wrong lessons, and those mistakes show up later as wrong predictions.
- How fair it is: if some groups or situations are missing from the data, the model will perform worse for them.
- How it handles the real world: a model trained only on narrow, clean examples often fails when it meets real users, real lighting or real handwriting.
Think of training data as a student’s textbook. A student with an outdated textbook and half the pages missing may not pass the exam. In the same way, without quality training data, an AI system will do its job poorly, if at all. That is the real importance of data in AI: it decides whether a model reaches its goals.
Do You Need Millions of People to Build AI?
No. You may need thousands or even millions of data points to build an efficient model, but you don’t need millions of people to prepare them. A relatively small, skilled team, often a few hundred people or fewer, can build the right training data for a specific use case.
What matters more than headcount is process. Clear labelling guidelines, trained annotators and regular quality checks produce consistent data. Without them, even a large team can produce data that confuses the model.
What Is Data Labelling and Annotation in Machine Learning?
Data labelling, also called data annotation, is the process of adding tags or notes to raw data so a model understands what it is looking at. It turns unmarked images, videos, text, speech or geospatial data into labelled data in machine learning that a model can learn from.
Good data labelling and annotation means every relevant point of an object is marked accurately. What that looks like depends on the data type:
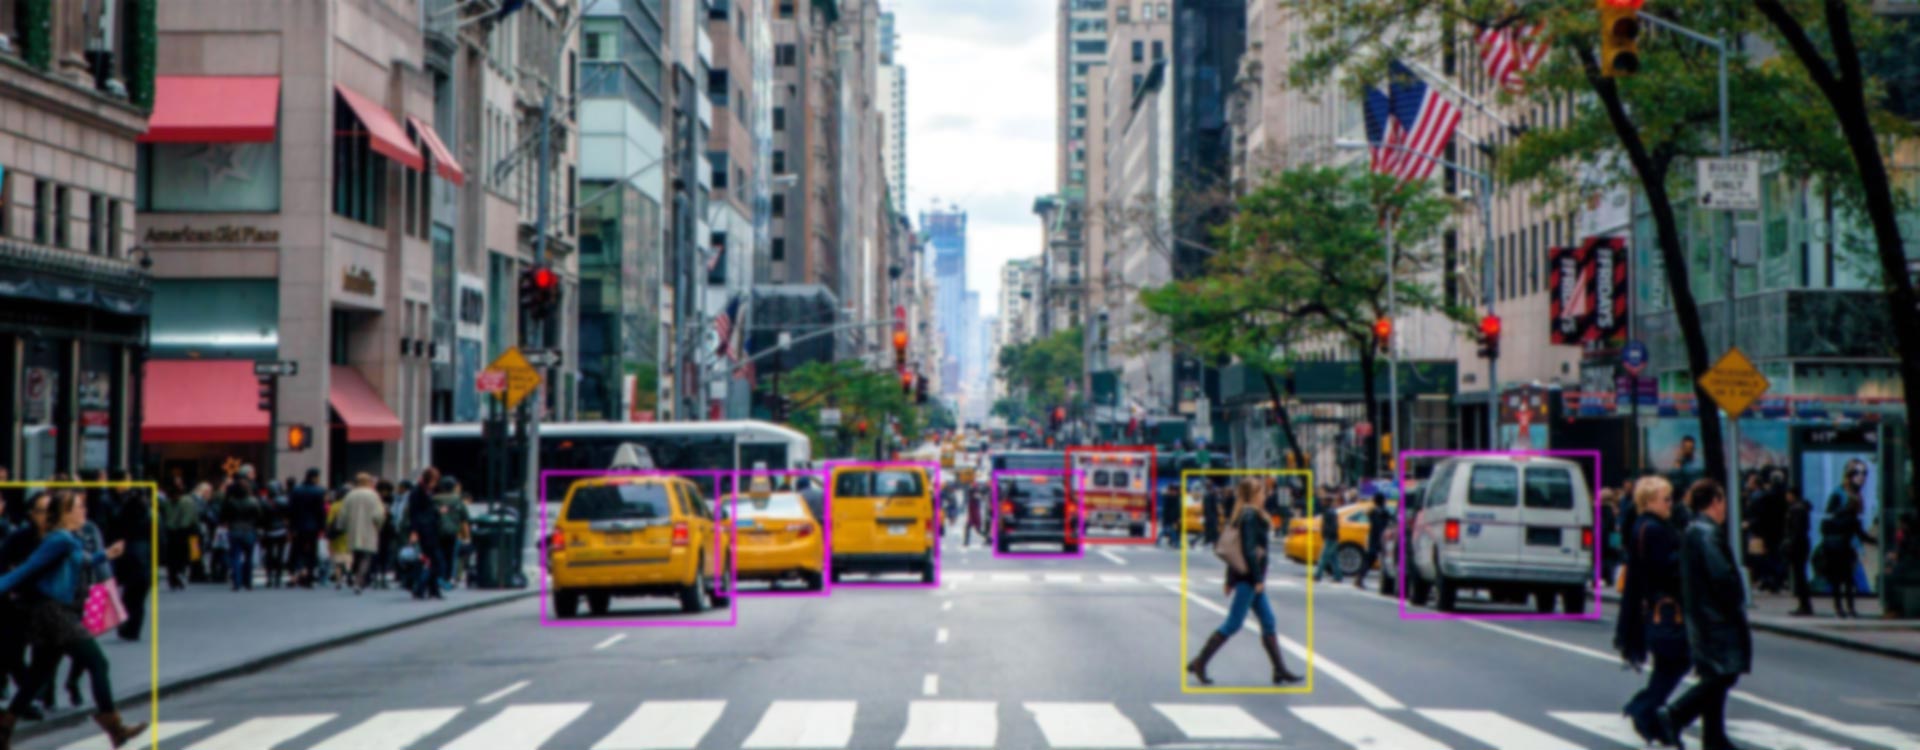
- Image annotation for computer vision: drawing bounding boxes around objects like cars and pedestrians, outlining shapes with polygons, or labelling every pixel through semantic segmentation. This is the core computer vision training data behind deep learning models for computer vision.
- Video annotation for machine learning: tracking objects across frames, such as following a vehicle through traffic or a person through a store.
- Text annotation: tagging names, places and dates, marking sentiment, or sorting documents into categories.
- Speech and audio annotation: transcribing spoken words, identifying speakers, or tagging background sounds.
- Geospatial annotation: marking roads, buildings or land features in maps and aerial images.
The quality of data annotation for machine learning directly affects how well a model learns. If two annotators label the same object differently, the model receives mixed signals. Consistent labelling is one of the least visible but most important parts of building training data.
Training and Testing Data in Machine Learning: What’s the Difference?
Most teams split their data into three sets: training data, validation data and test data. Training data teaches the model, validation data helps tune it, and test data gives a final, honest check. Keeping these three sets separate is the only way to know how well a model will really perform.
| Dataset | What it’s used for | When the model sees it |
Training data | Teaching the model patterns | Throughout training |
Validation data | Tuning settings, comparing versions, deciding when to stop training | During development, but the model never learns from it directly |
Test data | Final check of performance on unseen examples | Only once, at the end |
Understanding training data validation data and test data helps you avoid a common trap. If test examples leak into training, the model has effectively seen the exam answers in advance, and its scores will look better than they really are.
The basic rule for training and testing data in machine learning is simple: the model should never learn from the data used to judge it. That is what makes ai model testing meaningful.
What Is Model Validation in Machine Learning?
Model validation in machine learning is the process of checking whether a model performs well on data it has not seen before. It uses a separate validation set to measure results such as accuracy, precision and recall, so teams can catch problems before the model is deployed.
The most common problem validation catches is overfitting. That is when a model scores very well on its training data but performs poorly on new data, because it memorised the examples instead of learning the underlying pattern.
Validation also depends on labelled data. The team checks whether the model correctly detected or classified each object against the known labels. If those labels are wrong, you end up measuring the model against wrong answers.
How Does Cross Validation Work in Machine Learning?
Cross validation in machine learning is a way to get a more reliable picture of performance, especially when data is limited. In k-fold cross validation, the data is split into several equal parts. The model trains on all parts except one, then gets checked on the part left out. This repeats until every part has been used for checking once, and the results are averaged.
How Does Data Quality Affect Machine Learning Model Accuracy?
Data quality in machine learning directly controls how accurate, fair and reliable a model can be. Clean, consistent and representative data lets the model learn real patterns. Noisy or biased data teaches it mistakes, which lowers machine learning model accuracy once the model is used in the real world.
High-quality training data usually has these qualities:
- Accurate: labels match what is actually in the data.
- Consistent: the same object is labelled the same way every time, by every annotator.
- Representative: the data covers the full range of real situations, including edge cases.
- Relevant: the data matches the problem the model is meant to solve.
- Sufficient: there are enough examples for the model to see patterns, not just exceptions.
- Current: the data reflects how the world looks now.
Good data also saves time later. When training data is accurate from the start, model training is more reliable, and model validation and testing move faster because there are fewer errors to trace back and fix.
How to Prepare Data for Machine Learning
Preparing data for machine learning usually follows six steps:
- Collect raw data that matches your real use case.
- Clean it by removing duplicates, fixing errors and handling missing values.
- Label it using clear, written annotation guidelines.
- Review the labels through quality checks, such as a second annotator or spot audits.
- Split it into training, validation and test sets.
- Monitor and refresh the data after deployment, as real-world conditions change.
Much of the effort in model training in machine learning goes into steps two to four, not into the model itself. Teams training machine learning models often find that improving the data gives bigger gains than changing the algorithm.
How Much Training Data Do You Need?
There is no fixed number. The amount depends on how complex the task is, how many categories the model must tell apart, how much variation exists in the real world, and whether you start from a pre-trained model.
A simple classifier may work well with a few thousand good examples. A complex computer vision system may need millions. In most cases, a smaller set of accurate, representative data does better than a much larger set of messy data.
When Should You Use Data Annotation Services?
Data annotation services make sense when you need large volumes of labelled data, specialised labelling skills, or consistent quality that is hard to manage in-house. They let your data scientists and engineers focus on building and improving models instead of labelling data.
They are especially useful when you are scaling a model to new data types, working with complex formats like video or geospatial data, or starting a project without a trained annotation team.
Conclusion:
If you have wondered why image puzzles replaced the old word-based Captchas, the answer ties back to this whole topic. Today, web users are asked to identify traffic lights, road crossings, motorcycles and cars. Those clicks are a simple form of image labelling, the same kind of work that builds training data for AI.
Algorithms often get the credit, but reliable AI starts with reliable data. Accurate labelling, careful validation and a steady focus on data quality are what turn a promising model into one that works in the real world.
Happy training!
FAQs
1. What is the machine learning model training process?
The model is given labelled training data and adjusts its internal settings to reduce prediction errors. Its progress is checked on separate validation data, and training usually stops when validation results stop improving. A final test set then confirms how the model performs on new data. This is the core of model training in machine learning.
2. What is the difference between training data and test data?
Training data and test data do different jobs. Training data teaches the model patterns. Test data is kept completely separate and used only at the end, to check how well the model performs on examples it has never seen.
3. How does data quality affect AI model performance?
High data quality in machine learning reduces errors, noise and bias, so the model learns real patterns and performs better on new data. Poor data quality leads to inaccurate predictions, biased results and models that fail in real-world use.
4. Why is diverse training data important?
Diverse ai training data helps a model handle the full range of situations and people it will meet after deployment. If the data lacks variety, the model may perform poorly for underrepresented groups or situations, leading to unfair or inaccurate outcomes.
5. Are data annotation services worth it for small businesses?
Often, yes. Data annotation services give small teams access to trained annotators and quality checks without building an in-house labelling team. This helps them produce accurate training data and build reliable AI models without heavy upfront investment.
Happy Training!