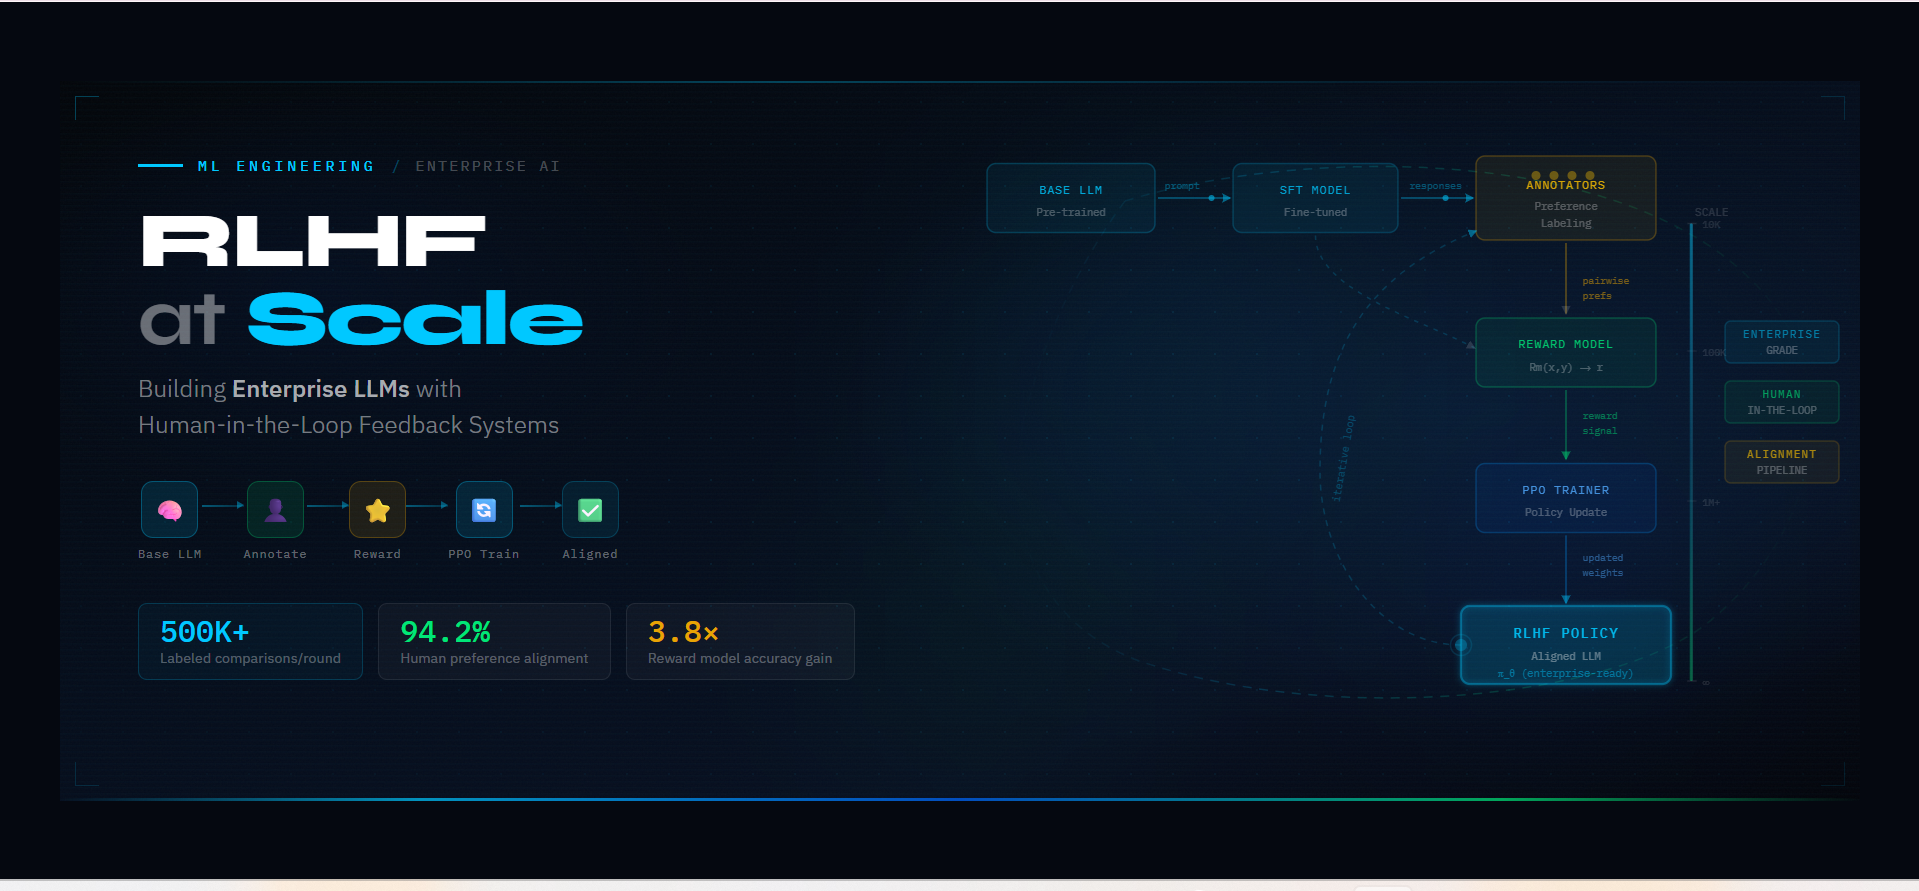
This article explores the critical role of Reinforcement Learning from Human Feedback (RLHF) and Human-in-the-Loop (HITL) systems in developing robust, accurate, and ethically aligned enterprise Large Language Models (LLMs) in 2026. We’ll delve into how integrating human feedback at scale enhances model performance, adaptability, and ethical decision-making, ultimately driving significant business value.
Key takeaways:
- RLHF in LLMs is crucial for continuous improvement through human feedback.
- HITL systems ensure LLMs align with business goals and ethical standards.
- Benefits include increased LLM accuracy, reduced errors, and adaptability to dynamic environments.
- Explore AI cost savings through faster deployment and reduced retraining.
- Understand the challenges of scaling RLHF, such as resource intensity and feedback consistency.
In the rapidly evolving landscape of enterprise-level Large Language Models (LLMs), the primary challenge extends beyond merely generating human-like text. It’s about ensuring these models deliver reliable, accurate, and context-sensitive outputs within complex, real-world business scenarios. This is precisely where Reinforcement Learning from Human Feedback (RLHF), combined with Human-in-the-Loop (HITL) systems, becomes indispensable.
As organizations increasingly deploy LLMs for diverse applications, from customer service and knowledge management to product recommendations and personalization, incorporating human feedback guarantees that these models remain aligned with specific business objectives and human expectations. This article will explore the significance of RLHF at scale, how HITL systems drive impact, and why they are fundamental to building successful enterprise LLMs in 2026.
What is RLHF in AI and How Does it Work for Enterprise LLMs?
Reinforcement Learning from Human Feedback (RLHF) is an advanced training methodology where AI models learn to fine-tune their responses or behavior based on signals provided by human evaluators. This process is particularly vital in enterprise settings, where LLMs must make nuanced decisions informed by specific contexts, business priorities, and real-world data.
In an RLHF framework, human evaluators assess the model’s outputs and provide feedback on how well they align with desired real-world expectations. For instance, in a customer support application, human feedback ensures that an LLM’s responses are polite, relevant, and appropriate for the given situation. This continuous feedback loop guides the model towards making better decisions, even in ambiguous or ethically sensitive scenarios, significantly boosting LLM accuracy.
Why Do RLHF and HITL Matter for Building Enterprise LLMs?
Enterprise LLMs are designed to handle a wide array of tasks, from processing customer queries to generating product recommendations. The inherent complexity of these tasks necessitates high-quality, domain-specific outputs. RLHF and HITL systems are instrumental in achieving this by addressing several key challenges:
1. Ensuring Contextual Understanding
Business requirements vary significantly across industries. LLMs must adapt to these specific contexts. For example, medical LLMs require a deep understanding of health terminology, while legal LLMs must accurately interpret contractual language. RLHF, powered by HITL feedback, enables enterprises to guide models through real-world context, allowing them to accurately interpret complex, industry-specific data.
2. Continuous Adaptation and Learning
Markets, customer preferences, and industry trends are in constant flux. An enterprise LLM trained only once risks becoming quickly outdated. Through RLHF, human feedback ensures that models continuously evolve, adapting to new data and feedback. This ongoing learning process is crucial for businesses aiming to remain responsive and competitive.
3. Ethical Decision-Making and AI Alignment
Enterprises have a responsibility to ensure their AI models adhere to ethical guidelines and avoid amplifying biases. Human evaluators are uniquely positioned to identify biases in model responses, such as gender or racial biases, and intervene in real-time to correct them. RLHF, combined with HITL feedback, is essential for achieving AI alignment, ensuring LLMs produce fair and ethically sound outputs.
4. Aligning Outputs with Business Objectives
Business models are designed to achieve specific goals, whether it’s enhancing customer support, streamlining internal operations, or increasing sales revenue. HITL feedback is vital for fine-tuning LLMs so that their outputs directly support strategic business objectives. Human evaluators guide the model to focus on relevant tasks and adjust its behavior to reflect shifting business priorities.
The ROI of RLHF and HITL Feedback for Enterprise LLMs
For data scientists and management teams, demonstrating the return on investment (ROI) for new technologies is paramount. RLHF and HITL provide measurable business benefits, including significant AI cost savings.
Faster Time-to-Market
By integrating RLHF and HITL feedback, enterprises can accelerate the deployment of LLMs. Human feedback ensures continuous model improvement during both training and post-deployment phases, which reduces the time spent on debugging and retraining. This leads to:
- Reduced Development Costs: Enterprises can avoid costly trial-and-error cycles often associated with traditional model training. By integrating human expertise, models are better aligned with desired outcomes from the outset.
- Streamlined Launches: With RLHF, models can be deployed sooner, with continuous human oversight enabling real-time adjustments, allowing businesses to scale faster than competitors.
Increased Accuracy, Reduced Errors
LLM accuracy directly impacts customer satisfaction, operational efficiency, and decision-making quality. By leveraging RLHF, LLMs become more adept at making contextually relevant and accurate decisions, which drives:
- Improved Customer Satisfaction: LLMs that consistently provide accurate responses lead to better customer experiences, enhancing loyalty and retention.
- Cost Savings: By preventing incorrect decisions or suboptimal outputs, RLHF and HITL can significantly reduce operational costs that arise from errors in automated processes.
Long-Term Value Creation
RLHF and HITL foster continuous improvement through ongoing human feedback. This means that over time, as the model interacts with new data and adapts to changes in the business environment, its performance steadily improves. This provides long-term value that surpasses the initial investment and contributes to sustained business success.
Human-in-the-Loop Feedback: The Backbone of Scaling RLHF
Scaling RLHF effectively requires a robust Human-in-the-Loop system to ensure continuous oversight, refinement, and monitoring. Here’s how HITL supports RLHF at scale:
1. Data Annotation and Labeling
At scale, high-quality data annotation is critical for effective AI model training. HITL ensures that data used for training is accurately labeled and contextually enriched, particularly in regulated industries like healthcare and finance. NextWealth provides precision HITL data labeling for object detection, segmentation, and video tracking (https://www.nextwealth.com).
2. Real-Time Model Validation
Once LLMs are deployed, HITL feedback ensures that outputs are continuously validated in real-time. This guarantees that critical outputs, such as customer support responses or legal documents, maintain high quality and remain aligned with human expectations.
3. Fine-Tuning Post-Deployment
After deployment, HITL ensures that the LLM remains aligned with evolving business goals. Continuous human feedback allows for the fine-tuning of LLM behavior, adapting it to shifting priorities and market demands. NextWealth offers expert RLHF, red teaming, prompt evaluation, and domain-specific dataset curation for LLMs (https://www.nextwealth.com).
4. Error Correction and Continuous Learning
HITL facilitates rapid error correction. If an LLM makes a mistake or provides inaccurate results, humans can intervene immediately, providing feedback to correct errors and refine the model for future interactions. This is key to how to improve LLM accuracy over time.
Key Challenges in Scaling RLHF for Enterprise LLMs
While RLHF and HITL are powerful tools, scaling them across an enterprise presents its own set of challenges:
1. Resource Intensity
Human feedback is inherently resource-intensive. As models scale, there’s an increasing need for qualified human evaluators to provide feedback. Enterprises must balance the human effort required for RLHF with the cost and time constraints of large-scale implementations. NextWealth’s 5,000+ specialists are trained, managed, and operating from Tier-2 India, providing a scalable solution (https://www.nextwealth.com).
2. Consistency and Quality Control
Maintaining consistent feedback can be challenging, especially when multiple evaluators are involved. Clear annotation guidelines and feedback protocols are critical to ensuring high-quality feedback and model reliability. NextWealth delivers high-quality data solutions for unmatched performance and reliability (https://www.nextwealth.com).
3. Managing Complex Use Cases
Enterprise LLMs often handle edge cases or rare scenarios that require specific human judgment. HITL systems must efficiently manage these cases by ensuring a well-organized feedback workflow that involves skilled annotators capable of interpreting complex situations.
How NextWealth Supports RLHF at Scale for Enterprise LLMs
At NextWealth, we specialize in scaling RLHF for enterprise-level LLMs with a human-centered approach. Our Human-in-the-Loop systems are designed to seamlessly integrate real-time human feedback with machine learning workflows, ensuring continuous improvement and adaptation to business needs. NextWealth has 5,000+ HITL specialists across 11 Tier-2 delivery centres (https://www.nextwealth.com/about).
We address the core challenges of RLHF at scale by:
- Optimizing human feedback workflows to minimize resource intensity.
- Implementing consistent feedback protocols to ensure the highest quality of data.
- Training expert annotators who bring industry-specific knowledge to the annotation process.
By leveraging NextWealth’s HITL expertise, enterprises can build LLMs that are accurate, ethically sound, and aligned with business objectives, ensuring long-term success and reliability. NextWealth provides human-in-the-loop content moderation, KYC verification, policy enforcement, and fraud prevention (https://www.nextwealth.com).
Final Thoughts on RLHF in LLMs for 2026
Scaling RLHF with Human-in-the-Loop feedback is essential for building enterprise-level LLMs that are both accurate and adaptive. By integrating human insight with machine learning, businesses can create systems that not only meet current needs but are also resilient and capable of evolving with future challenges. This approach is critical for successful enterprise AI development in 2026.
At NextWealth, we empower enterprises to navigate these challenges by providing structured, human-led annotation processes that ensure high-quality, reliable models. Our approach enables businesses to deploy systems that are aligned with real-world requirements, leading to improved performance and sustained growth. NextWealth is an AI data operations company founded in 2009 in Bengaluru, India (https://www.nextwealth.com/about).
Frequently Asked Questions About RLHF and LLMs
What is RLHF in AI?
RLHF in AI, or Reinforcement Learning from Human Feedback, is a machine learning technique where human evaluators provide feedback on an AI model’s outputs. This feedback is then used to train a reward model, which in turn guides the AI to generate more desirable and aligned responses, significantly improving its performance and safety.
How does human feedback AI improve LLM accuracy?
Human feedback AI improves LLM accuracy by directly correcting errors and guiding the model toward preferred behaviors. Human evaluators identify nuanced mistakes, biases, or misinterpretations that automated metrics might miss, allowing the LLM to learn from specific examples and continuously refine its understanding and generation capabilities.
Will LLM be considered as practice for AI alignment?
Yes, LLMs are increasingly considered a crucial practice ground for AI alignment. The complexity and broad applicability of LLMs make them ideal for developing and testing methods like RLHF to ensure their outputs are safe, ethical, and aligned with human values and intentions, preventing unintended or harmful behaviors.
What are some RLHF alternatives for improving LLM performance?
While RLHF is highly effective, some RLHF alternatives include supervised fine-tuning with expert-labeled data, constitutional AI (using a set of principles to guide model behavior without direct human preference labels), and direct preference optimization (DPO), which simplifies the training process by directly optimizing for human preferences.
How does RLHF contribute to AI cost savings for enterprises?
RLHF contributes to AI cost savings by accelerating model deployment and reducing the need for extensive manual corrections post-launch. By continuously improving model accuracy and alignment through human feedback, enterprises can minimize errors, reduce operational overhead, and avoid costly retraining cycles, leading to more efficient and reliable AI systems.