Introduction
Every computer vision model is only as trustworthy as the boundaries it was trained on. A self-driving car deciding whether to brake, a radiologist’s AI assistant flagging a suspicious mass, a retail system counting stock on a shelf all of these depend on the model correctly understanding where one object ends and the background begins. When that boundary is fuzzy, the model doesn’t just get “slightly less accurate.” It starts seeing things that aren’t there.
This is the false positive problem, and it is one of the most persistent obstacles to deploying computer vision at scale. A model that flags a shadow as an obstacle, or normal tissue variation as a tumor, quickly loses the trust of the people relying on it even if it’s right 95% of the time. Reducing that error rate isn’t just a modeling problem; it starts much earlier, at the point where raw pixels are turned into labeled training data.
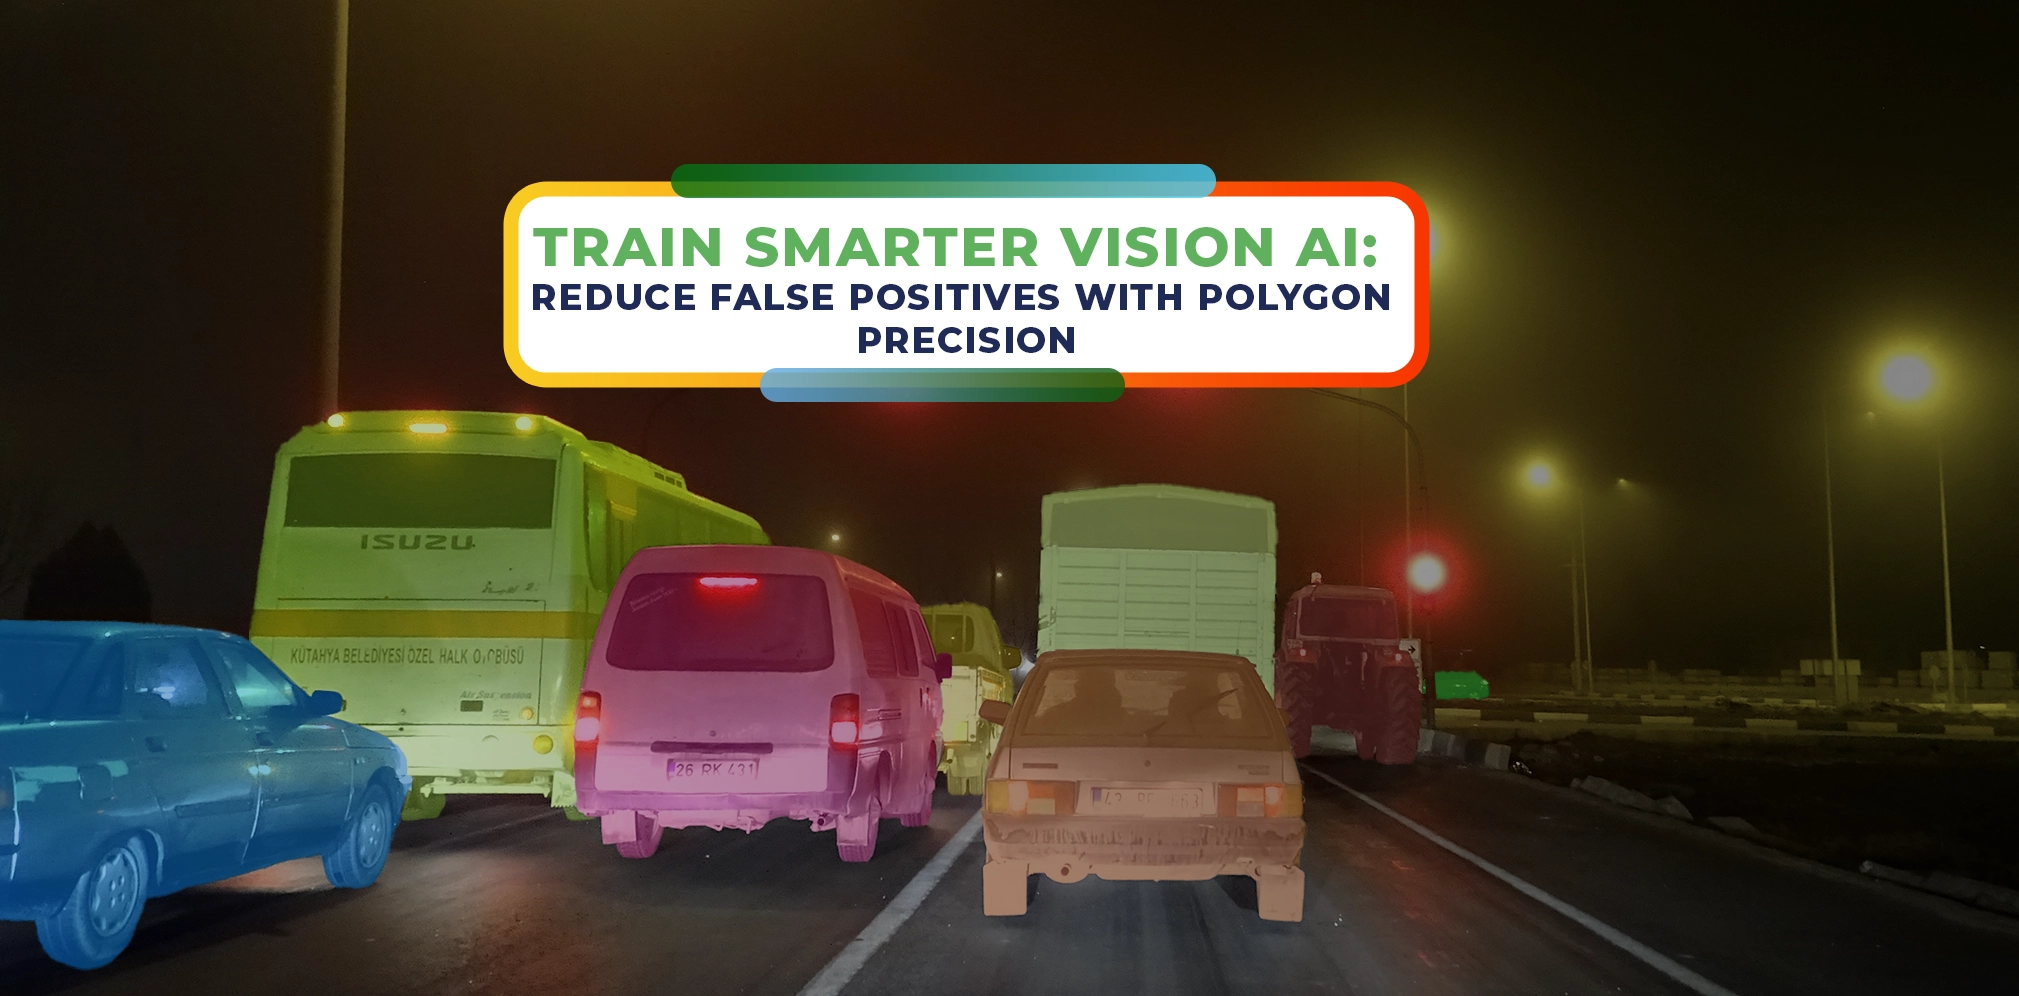
That is where a polygon annotation tool earns its place in the computer vision pipeline. Unlike rectangular bounding boxes, which approximate an object’s location, polygon-based labeling traces the actual contour of an object point by point, giving the model a training signal that matches reality far more closely. In this article, we look at why annotation precision matters so much, how polygon-based labeling reduces errors, and where it delivers the greatest impact.
Why Imprecise Labels Lead to a High False Positive Rate
Most computer vision datasets still rely heavily on bounding boxes because they’re fast to draw. But speed comes at a cost. A rectangular box drawn around an irregular object a person mid-stride, a car partially hidden behind a pole, a tumor with an uneven edge inevitably includes pixels that don’t belong to the object at all.
That extra “noise” doesn’t just sit passively in the dataset. The model learns from it. Over thousands of training examples, it starts associating background clutter, shadows, or adjacent objects with the target class itself. The result, once the model is deployed, is a false positive rate that’s higher than it should be: shadows mistaken for pedestrians, overlapping shelf items miscounted as a single product, healthy tissue occasionally flagged alongside an actual anomaly.
A few common failure patterns show up again and again in loosely labeled data:
- Background bleed — bounding boxes around irregular shapes capture surrounding context that the model wrongly treats as part of the object.
- Ambiguous overlaps — when two objects sit close together, a rectangular box can’t cleanly separate them, so the model struggles to tell them apart later.
- Inconsistent edges — without a precise outline, the model never learns exactly where an object’s boundary sits, which shows up as jittery or oversized detections at inference time.
These aren’t rare edge cases they’re a direct, measurable consequence of the annotation method chosen at the start of the pipeline. Improving computer vision data labeling quality is, in effect, the most direct lever teams have for reducing downstream error rates.
Consider a warehouse camera system trained to count boxes on a pallet. If the bounding boxes used during training routinely include slivers of neighboring boxes or shadowed gaps between them, the model doesn’t learn “this is one box” it learns “this is roughly this size and shape, plus whatever happens to be nearby.” Multiply that ambiguity across a dataset of tens of thousands of images, and the model’s confidence scores become unreliable long before anyone notices a pattern in production. By the time a false positive rate shows up as a business problem misrouted inventory, a safety alert nobody trusts anymore, a radiologist starting to second-guess the AI’s flags the root cause is usually months old and buried in the original labeling decisions.
How Polygon Annotation Helps Reduce False Positives
Polygon annotation provides a shape-specific alternative to bounding boxes by tracing the true outline of an object. This leads to significantly tighter and more accurate data.
- Minimized Background Interference: Polygon labels exclude surrounding pixels, reducing the ‘noise’ the model is exposed to.
- Higher Learning Fidelity: Models trained on sharply contoured objects can distinguish better between similar classes (e.g., person vs. mannequin, tree vs. pole).
- Improved Generalization: Clean data input enhances the model’s performance when exposed to real-world variations, decreasing the false positive rate.
Companies that adopted advanced annotation techniques like polygons saw up to a 25–40% improvement in detection precision over traditional bounding box approaches. i.e. when using pixel-wise annotations over bounding boxes.
Real-World Applications Where Polygon Annotation Excels
Polygon annotation finds critical application across sectors where precision isn’t just a preference—it’s a requirement.
- Autonomous Mobility: For Level 3+ ADAS systems, vehicles must interpret road scenes with nuance—differentiating between drivable and non-drivable areas, lane boundaries, and temporary obstacles. Polygons allow for accurate contouring of vehicles, traffic cones, and irregular road shapes, leading to safer decision-making.
- Healthcare: In radiology and histopathology, precise localization of abnormalities is critical. Polygons help trace tumor boundaries more effectively than rectangular annotations, minimizing misdiagnps 85is risks.
- Retail & ECommerce: For planogram compliance and shelf monitoring, products often appear stacked, occluded, or partially rotated. Polygon annotation enables granular identification of items despite visual clutter.
- Satellite & Aerial Imagery: Buildings, roads, farmlands, and water bodies rarely have rectangular outlines. Polygon annotation ensures high-accuracy mapping essential for urban planning, agriculture, and disaster response.
Best Practices in Polygon Annotation
Despite its benefits, polygon annotation can be time-intensive and error-prone if not managed correctly. At scale, accuracy and speed must coexist. Industry leaders implement the following best practices:
- Clear SOPs & Labeling Guidelines: Annotation complexity varies by domain. Detailed instructions on class hierarchies, occlusion rules, and edge handling are critical.
- Tooling Optimization: Advanced annotation tools like CVAT, V7, or Taskmonk with smart snapping, auto-segmentation, and QA workflows significantly enhance speed and consistency.
- Human-AI Collaboration: Semi-automated suggestions combined with human judgment provide the best of both worlds.
- Multi-Tiered QA: Double-blind reviews, gold-standard audits, and real-time feedback loops maintain annotation integrity.
NextWealth’s Edge: Human-in-the-Loop for Polygon Precision
At NextWealth, our HITL-powered polygon annotation workflow brings domain-aware humans and precision-driven technology together.
- Domain-Specific Expertise: Our annotators are trained in verticals like automotive, geospatial, and medical imaging—ensuring context-rich labelling.
- Proven QA Mechanism: Every annotation passes through a 2-stage verification pipeline, leveraging internal benchmarking tools and subject matter audits.
- Flexible Workflow Integration: We customize annotation layers, complexity tiers, and formats as per client requirements—delivering production-ready datasets.
- Quantifiable Outcomes: In a recent ADAS perception project, switching from bounding box to polygon annotation helped reduce false positives by over 32%, while maintaining 99.3% annotation accuracy across 250K frames.
Our human-in-the-loop advantage ensures annotations are not just accurate—but also explainable and auditable, aligning with industry trends around Responsible AI.
Conclusion
In the race to scale vision AI, training data is the fuel. But not all fuel is created equal. Reducing false positives begins at the annotation level — and polygon annotation emerges as a clear winner for tasks demanding spatial accuracy & high context fidelity.
As industries adopt AI to automate critical decisions, the importance of precise annotations becomes non-negotiable. Organizations that invest in high-quality data pipelines will build models that not only perform better but are also safer, more compliant & more trusted.
At NextWealth, we help companies deploy smarter, sharper AI by getting their data annotation right —the first time!
Ready to elevate your vision AI with polygon precision? Connect with our annotation experts today at:
Frequently Asked Questions
What is polygon annotation in computer vision?
Polygon annotation is a method of labeling images by drawing many connected points to trace the exact shape of an object, instead of just a rectangle. This gives AI models much more accurate training data.
Why do computer vision models make false positives?
False positives happen when models are trained on imprecise or noisy labels — for example, bounding boxes that include background or shadows — causing the AI to incorrectly detect objects that aren’t actually there.
How does polygon annotation reduce computer vision errors?
By tightly following an object’s real outline, polygon annotation removes background noise and gives the model clear boundaries to learn from, helping it distinguish similar or overlapping objects more precisely.
Where is precise polygon annotation most useful?
It’s especially helpful in safety‑critical use cases like autonomous vehicles, healthcare imaging (e.g., tumor tracing), retail shelf analysis, and satellite mapping — where small errors can cause big problems.
What are the best practices for polygon annotation quality?
Use clear SOPs and labeling rules, advanced tools with snapping and auto‑assist features, human‑AI collaboration, and multi‑tier quality checks to keep annotations both accurate and consistent at scale.
How does NextWealth’s HITL polygon annotation improve AI performance?
At NextWealth, we combine trained domain experts with advanced HITL workflows to produce highly precise polygon annotations that reduce false positives and boost AI accuracy for real‑world computer vision systems.