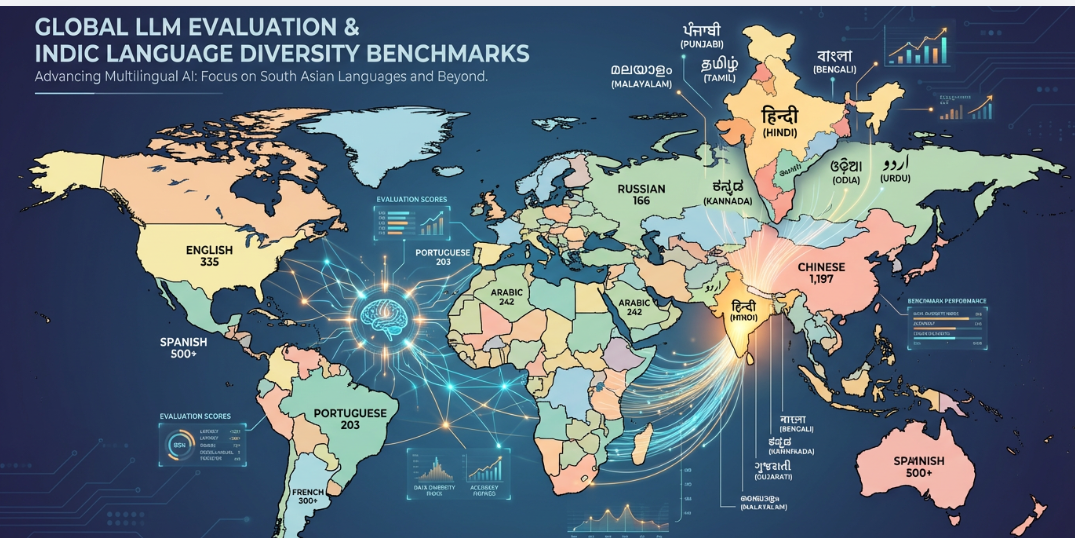
As large language models (LLMs) continue to advance, evaluating their performance, safety, and applicability has become a critical concern. Globally, research has matured to incorporate multi-dimensional benchmarks addressing robustness, fairness, factuality, and task generalization across domains and modalities. Despite these advances, significant gaps remain in evaluating LLMs for low-resource languages, particularly those in the linguistically diverse Indian context. This article surveys the current landscape of LLM evaluation frameworks and highlights the urgent need for Indic-specific benchmarking. We introduce IndicLLM-Eval, a contextualized evaluation framework that reflects the cultural, linguistic, and societal nuances of India, enabling equitable and safe deployment of LLMs across one of the most linguistically diverse populations in the world.
Introduction: The Challenge of LLM Evaluation for Languages
Large language models (LLMs) like GPT-4, Claude, PaLM/Gemini, and LLaMA have revolutionized natural language understanding and generation. However, evaluating their capabilities, especially across a diverse set of real-world applications, remains a central challenge. Traditional NLP metrics such as BLEU or F1 fail to capture the complexity of LLM behavior, including contextuality, multi-turn reasoning, and socio-linguistic sensitivity. While global benchmarks like HELM, MMLU, and BIG-bench have set the standard for English and high-resource languages, they fall short in addressing the intricacies of Indic languages. With 22 scheduled languages, hundreds of dialects, and complex socio-political contexts, India demands a new, culturally grounded approach to LLM evaluation.
Existing LLM Evaluation Frameworks: A Global Perspective
To design meaningful benchmarks for Indic LLMs, it is necessary to understand the landscape of existing evaluation frameworks. Over the past few years, the research community has proposed a wide array of benchmarks to assess various facets of language model performance, from general-purpose reasoning to domain-specific knowledge, and from safety testing to cultural sensitivity. This section offers a detailed review of these global frameworks, laying the groundwork for why a specialized Indic evaluation suite is required.
NIST, UK AI Safety Institute: These organizations are piloting public-sector evaluation frameworks to assess LLMs for national and international safety standards. They represent a shift toward regulatory benchmarking beyond academic research.
HELM (Holistic Evaluation of Language Models): From Stanford, HELM provides a broad evaluation framework that assesses LLMs across multiple dimensions including fairness, calibration, robustness, and efficiency. HELM is particularly influential for its emphasis on standardizing comparisons across tasks and models.
MMLU (Massive Multitask Language Understanding): This benchmark assesses general knowledge across 57 academic disciplines such as law, history, medicine, and philosophy. It is a staple benchmark for testing the breadth of LLM capabilities.
BIG-bench (Beyond the Imitation Game): Consists of over 200 tasks designed by a large community to evaluate LLMs on creative, ethical, and reasoning-based challenges that go beyond traditional NLP tasks.
HumanEval, LiveCodeBench: These benchmarks target code generation tasks. HumanEval evaluates functional correctness by executing code snippets, while LiveCodeBench integrates human evaluations and tests model performance in interactive coding environments.
FinBench, LegalBench, MultiMedQA: These are domain-specific benchmarks designed to evaluate models in finance, legal, and medical domains respectively. They assess the ability of LLMs to understand specialized vocabulary, structured documents, and perform expert reasoning.
SafetyBench, AgentHarm: These frameworks evaluate the safety of LLMs by prompting them with adversarial or harmful queries. SafetyBench focuses on social bias and toxicity, while AgentHarm evaluates harm potential in agent-based deployments.
M3Exam, CDEval: Both these benchmarks aim to evaluate multilingual and cultural competence in LLMs. M3Exam provides multilingual exam-style questions, while CDEval tests for alignment with diverse cultural norms.
LongBench, AdaLEval: These frameworks focus on long-context tasks, a critical ability for LLMs used in education, healthcare, or legal analysis. They test models’ ability to reason across long documents and follow multi-step instructions.
AIuminate, PromptBench: AIuminate, by MLCommons, introduces benchmarks for real-world safety, bias, and trust. PromptBench uses adversarial prompting techniques to measure model robustness and variation in generated outputs.
Why Global AI Benchmarks Miss India’s Linguistic Diversity?
Despite global progress in the evaluation of large language models (LLMs), substantial gaps persist when these methodologies are applied to Indic languages and contexts. These gaps are not only technical but deeply intertwined with linguistic diversity, socio-cultural complexity, and regional disparities in data availability. Below, we elaborate on the most critical limitations that currently hinder the accurate and fair evaluation of LLMs in India.
Limited Benchmark Coverage Across Indic Languages
Language in India is inseparable from its cultural and social context. Yet, most existing benchmarks fail to reflect the intricate interplay of cultural expressions, idiomatic usage, honorifics, and regional dialectal differences that characterize Indic communication. For instance, expressions of politeness, familial hierarchy, and respect (through pronouns, verbs, tone) vary dramatically between regions and even social strata. LLMs that are not evaluated on these subtle but essential elements risk producing content that is contextually incorrect, socially inappropriate, or even offensive. A culturally naive evaluation methodology can therefore lead to flawed assumptions about model competence.
Inadequate Capture of Cultural Expressions and Linguistic Nuance
Language in India is inseparable from its cultural and social context. Yet, most existing benchmarks fail to reflect the intricate interplay of cultural expressions, idiomatic usage, honorifics, and regional dialectal differences that characterize Indic communication. For instance, expressions of politeness, familial hierarchy, and respect (through pronouns, verbs, or tone) vary dramatically between regions and even social strata. LLMs that are not evaluated on these subtle but essential elements risk producing content that is contextually incorrect, socially inappropriate, or even offensive. A culturally naïve evaluation methodology can therefore lead to flawed assumptions about model competence.
Data Scarcity, Imbalance, and Dialectal Fragmentation
Fragmented Datasets and Inadequate LLM Evaluation Metrics
Beyond data scarcity, existing Indic language datasets suffer from fragmentation and limited annotation quality. Many publicly available corpora are derived from English translations or constrained to formal domains such as government documents and news text, offering little coverage of conversational language, informal registers, or domain-specific usage. Annotations, where present, are often inconsistent or insufficiently validated, undermining their reliability for benchmarking.
Furthermore, evaluation practices rely predominantly on surface-level automated metrics such as BLEU, ROUGE, and F1-score. While useful for controlled generation or classification tasks, these metrics fail to capture semantic adequacy, pragmatic intent, discourse coherence, and sociolinguistic appropriateness—dimensions that are particularly critical for morphologically rich and context-sensitive Indic languages. As a result, current metrics provide an incomplete and often misleading picture of model performance.
Absence of Safety and Harm Evaluation for Indic Social Contexts
Finally, existing LLM safety and bias evaluation frameworks are largely misaligned with the socio-political realities of India. While Western benchmarks emphasize racial or gender bias, they rarely account for harms arising from caste hierarchies, religious polarization, regional discrimination, or linguistic marginalization. These factors are deeply embedded in both historical and contemporary Indian discourse and can be subtly reproduced or amplified by LLMs. The absence of Indic-specific adversarial prompts, bias taxonomies, and harm detection benchmarks means that models may pass standard safety evaluations while still generating content that reinforces stigma, misinformation, or intergroup hostility. Without evaluation methodologies grounded in Indian social contexts, claims of model safety and fairness remain incomplete and potentially misleading.
Introducing IndicLLM-Eval: A Framework for Indian Language LLMs
While large language model (LLM) evaluation has advanced significantly in high-resource languages like English, there is a critical and urgent need to develop evaluation frameworks that address the linguistic and socio-cultural realities of India. The Indian subcontinent presents a uniquely complex linguistic ecosystem: it has over 20 constitutionally recognized languages, thousands of dialects, multiple scripts, and an extraordinary degree of intra-sentence code-mixing in daily communication. However, current global benchmarks are ill-equipped to assess LLM performance in such a multilingual, multicultural, and socially sensitive environment.
Indic languages are not merely translations of English; they carry distinct syntactic structures, morphological patterns, honorifics, idioms, and expressions of hierarchy and social identity. Moreover, many Indian languages co-occur in conversation, often mixing with English (e.g., Hinglish, Tanglish, Benglish), creating hybrid language forms that require contextual reasoning and deep linguistic grounding. Without a benchmark that can capture these nuances, LLMs trained or fine-tuned for India will continue to be evaluated using proxies that do not reflect actual usage scenarios or safety considerations.
To address these challenges, we propose IndicLLM-Eval, a dedicated evaluation framework designed to benchmark the performance, fairness, safety, and usability of large language models in Indian linguistic contexts. The framework integrates culturally grounded tasks, multilingual support, and real-world datasets to ensure comprehensive and context-aware evaluation.
Components of the IndicLLM-Eval Framework
[Image: Diagram illustrating the IndicLLM-Eval framework components and pipeline]
Core Design Principles of IndicLLM-Eval
IndicLLM-Eval is grounded in the following design principles:
- Inclusivity: Prioritizes linguistic equity by evaluating across both high- and low-resource languages.
- Cultural Sensitivity: Tests for context-specific reasoning, including moral, religious, and familial domains.
- Human-Centricity: Emphasizes human judgment in assessing responses beyond numerical scores.
- Safety and Fairness: Builds on culturally contextualized definitions of harm and appropriateness, crucial for IndicSafe practices.
- Modularity: Allows task-specific and domain-specific plug-ins for evaluating specialized use cases.
Why is the IndicLLM-Eval Framework Needed in 2026?
India is becoming one of the largest deployment grounds for AI-powered systems, from vernacular search engines to customer service bots in native languages. However, the lack of culturally aware and safety-conscious evaluation frameworks poses a real risk. Without robust assessments, LLMs may reinforce caste discrimination, misinterpret regional idioms, or produce biased content that undermines user trust. IndicLLM-Eval fills this void by setting rigorous standards that are aligned with Indian sociolinguistic realities and inclusive digital transformation goals. This framework is vital for ensuring AI fairness and ethical AI development specifically for India.
The IndicLLM-Eval Pipeline: Benchmarking LLMs for Indian Languages
Evaluating language models in the multilingual and culturally diverse Indic context demands a specialized and structured approach. The IndicLLM-Eval pipeline is designed to systematically assess model performance across a range of tasks, languages, and sociolinguistic dimensions. It combines linguistic annotation, task-based benchmarking, human and automated evaluation, and bias auditing to ensure robust and responsible LLM development for India.
We summarize the process in the following seven steps:
Step 7: Feedback Loop
This completes the loop and feeds into the input data collection step 1, ensuring continuous improvement and adaptation of the framework.
Step 1: Input Data Collection
Curate diverse datasets across multiple Indic languages from domains like government records, social media, academic text, and conversational data, ensuring inclusion of both formal and informal registers.
Step 2: Linguistic Annotation & Code-Mix Parsing
Apply fine-grained linguistic annotations (e.g., POS tagging, NER) and parse code-mixed content to capture language switches, transliterations, and structural inconsistencies typical of multilingual Indian usage.
Step 3: Task Categorization
Organize the dataset into representative evaluation tasks:
Question Answering (QA) – including specific focus on IndQA and IndQA benchmark datasets.
Summarization
Sentiment Analysis
Natural Language Inference (NLI)
Dialogue Understanding
Step 4: Evaluation Modules
Deploy a multi-layered evaluation strategy:
Automated Metrics (BLEU, ROUGE, Accuracy)
Human Judgments (fluency, coherence, factual consistency)
Bias Audit (gender, caste, religion, regional) – central to LLM bias evaluation.
Long-Context Testing (retention, coherence in extended documents)
Step 5: Score Aggregation & Reporting
Aggregate results across tasks and metrics into composite scores. Present detailed performance profiles for transparency and comparability.
Step 6: Leaderboard + Safety Certification
Publish model rankings on a public Indic LLM leaderboard and assign Safety Certifications based on compliance with ethical and bias mitigation benchmarks. This step is crucial for promoting LLM safety within the Indian context.
Future Research Directions for Indic Language Models
To ensure the development of robust and inclusive language models for the Indian subcontinent, future research must continue to refine and expand frameworks like IndicLLM-Eval. This includes developing more sophisticated LLM performance metrics that capture the nuances of code-mixing and cultural context, as well as creating larger, more diverse, and ethically sourced datasets for low-resource Indic language models. Further work on AI ethics India is also paramount to address emerging challenges and ensure responsible AI deployment.
Frequently Asked Questions about IndicLLM-Eval
What is IndicLLM-Eval?
IndicLLM-Eval is a specialized framework designed to benchmark large language models (LLMs) for Indian languages. It focuses on evaluating performance, fairness, and safety within India’s unique linguistic and cultural contexts, addressing gaps left by global benchmarks.
Why is benchmarking linguistic diversity of large language models important?
Benchmarking linguistic diversity is crucial because it ensures AI models perform accurately and equitably across all languages and cultures. Without it, models trained predominantly on high-resource languages can perpetuate biases or fail to understand the nuances of diverse linguistic communities, like those in India.
How does IndicLLM-Eval address AI fairness?
IndicLLM-Eval addresses AI fairness by incorporating culturally contextualized bias audits. It specifically evaluates LLMs for harms related to caste, religion, regional discrimination, and linguistic marginalization, which are critical social considerations in India.
What is the Indic LLM leaderboard?
The Indic LLM leaderboard is a public ranking system within the IndicLLM-Eval framework. It showcases the performance of various LLMs based on their compliance with ethical and bias mitigation benchmarks, promoting transparency and healthy competition in the development of Indian language LLMs.
What is IndQA?
IndQA refers to Question Answering tasks specifically tailored for Indian languages. Within the IndicLLM-Eval framework, IndQA datasets are used to evaluate an LLM’s ability to accurately understand and respond to questions in diverse Indic linguistic contexts, including code-mixed scenarios.